
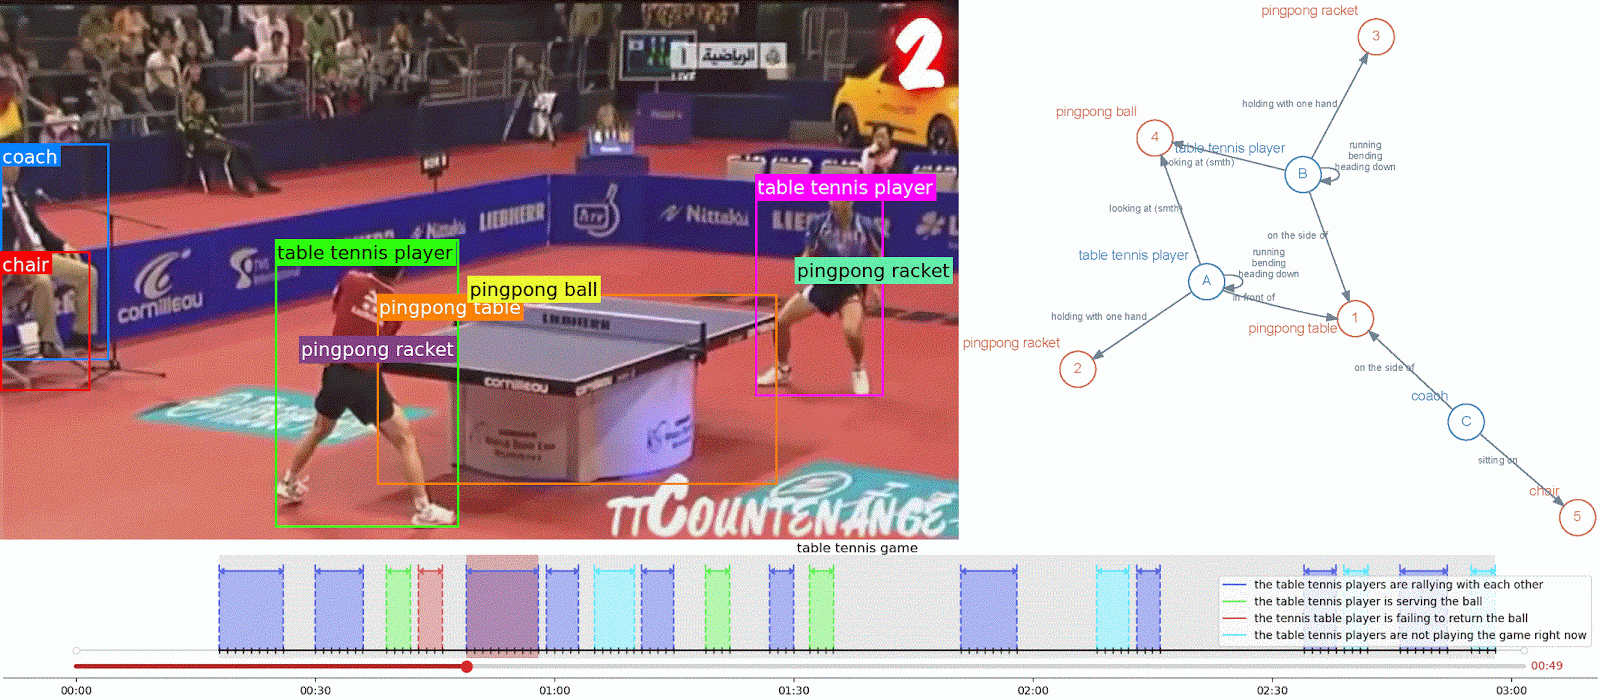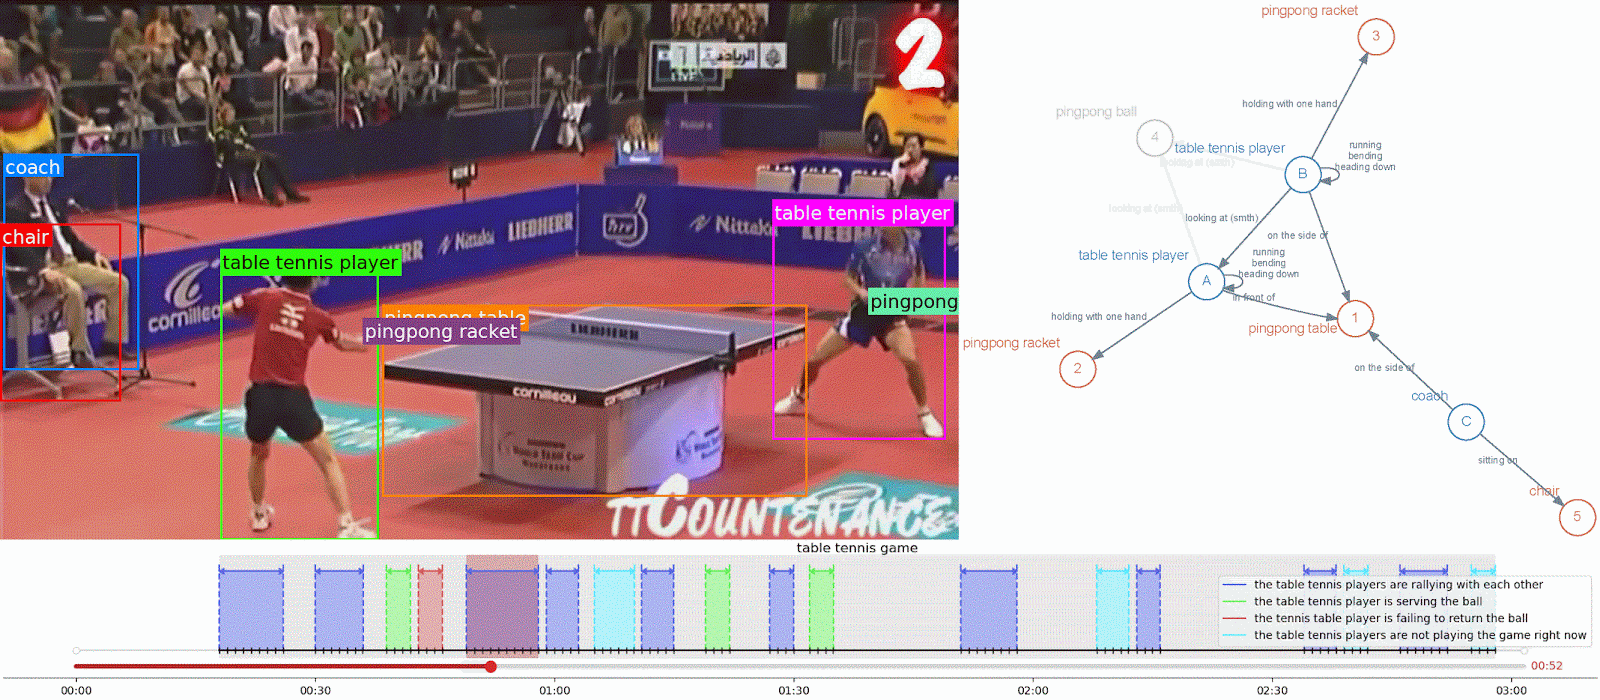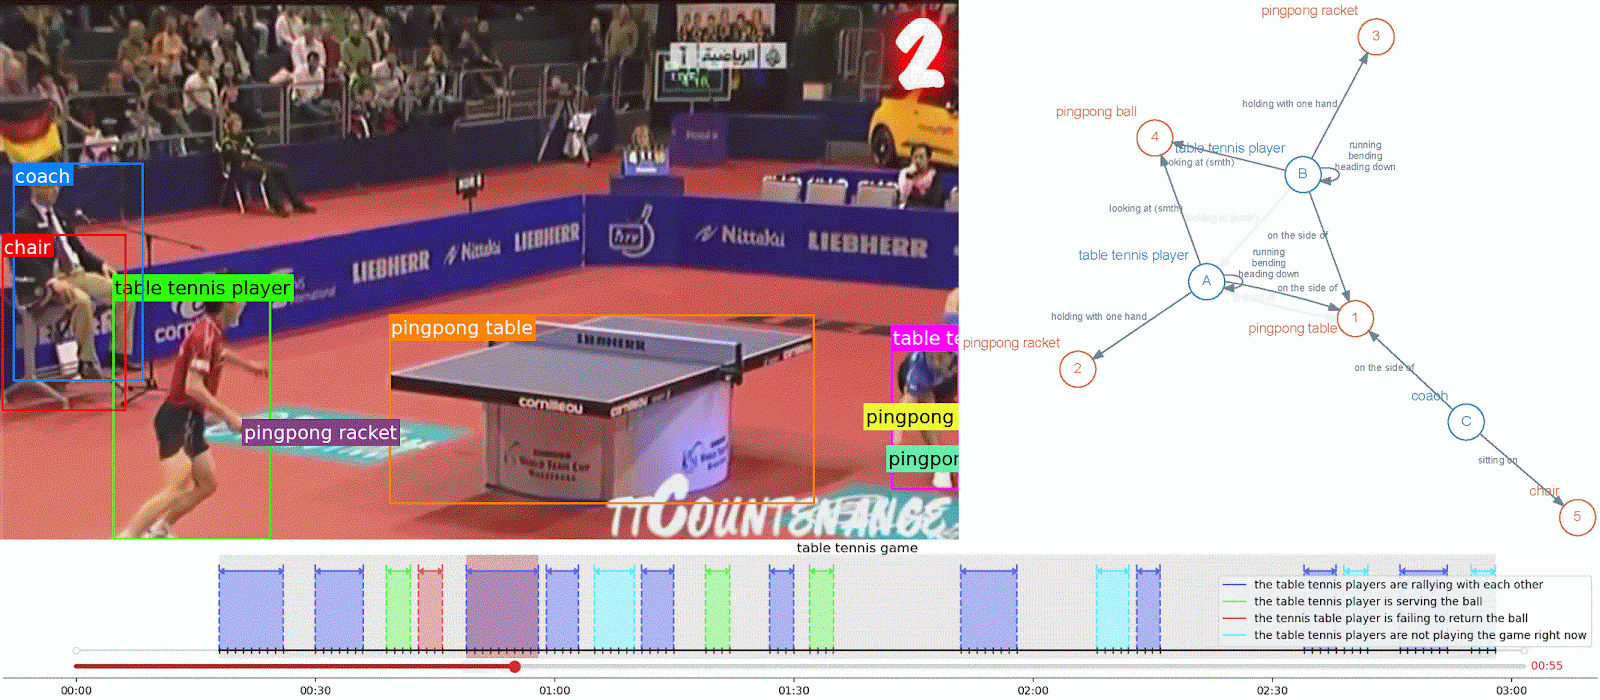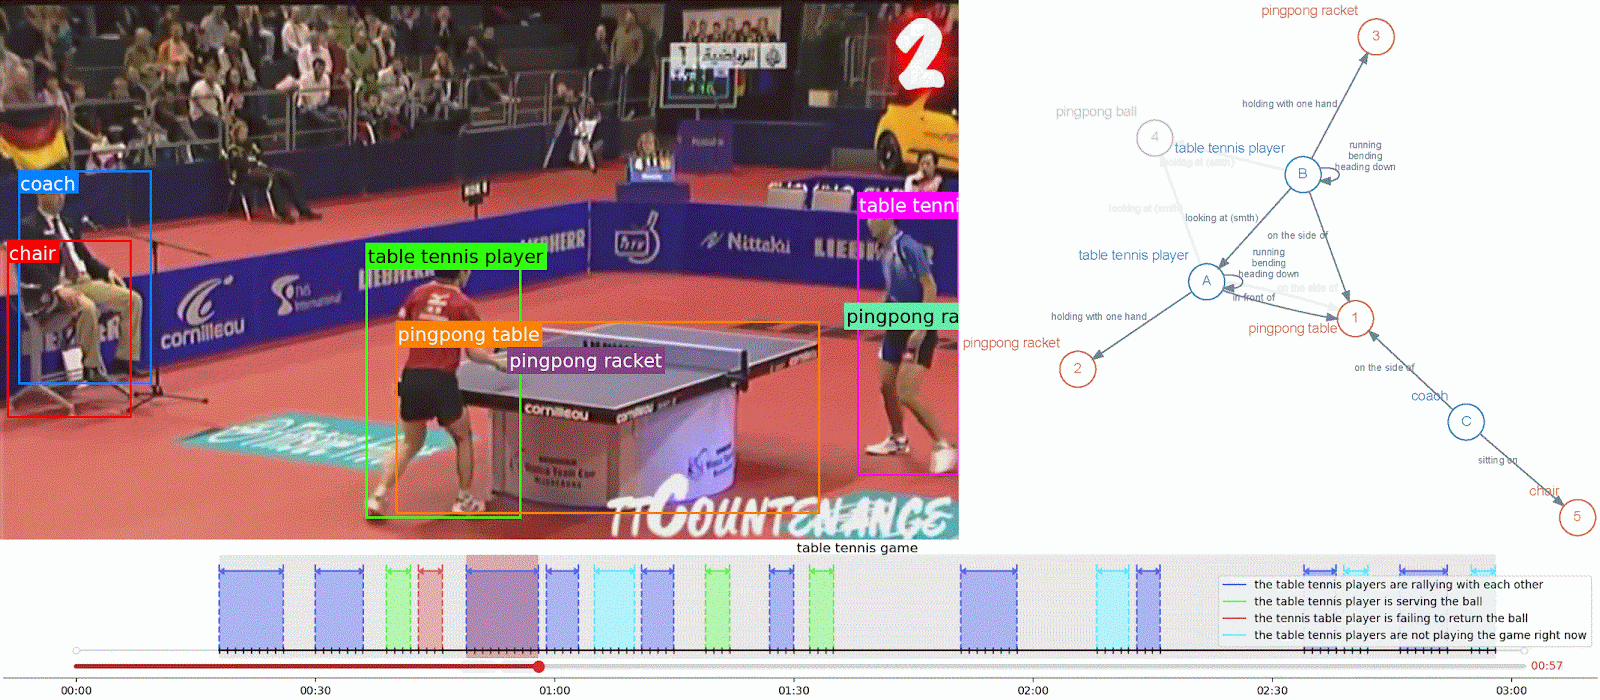
We are working on a series of works around Video Understanding & Motion Analysis, focusing on developing models to understand human motion, activities, and behaviors in real-world environments from videos. This work includes building systems for video action recognition and analysis, 3D human pose estimation, mesh reconstruction, and multimodal motion generation driven by text or audio inputs. We develop novel video language models and generative models centered around humans and their actions in videos. These models have broad applications, including healthcare, human-computer interaction, sports analysis, and entertainment, enhancing the ability to analyze and interpret human actions through various mediums. Key aspects of the project involve creating foundation models and leveraging multi-modal data such as video, motion capture, depth sensors, and language.